
Este artículo está actualmente disponible solo en inglés.Ver en inglés →
Live chat outsourcing means paying an outside provider to staff the chat window on your site or app, with human agents who answer under your routing rules, hours, and service levels. It suits brands that need staffed conversations without building a full queue in-house.
What it costs depends on three things: the hours you need covered, how complex the conversations are, and how many chats each human agent handles at once. Public rates start at US$0.20 for each interaction and US$5.80 per hour for a dedicated agent, and the full price table is further down.
Most quotes for outsourced chat lead with a response time, often with a number attached. Few of them state the figure that decides whether that number is achievable: concurrency, the count of conversations one human agent carries at the same time.
That absence matters more than it sounds.
On this page
- Why a chat quote without concurrency isn’t a quote
- What to ask instead
- Who takes which chat
- What outsourced live chat support services actually cost
- Dedicated live chat outsourcing vs a shared team
- 24/7 live chat outsourcing: nights and weekends
- How to compare outsourced live chat providers
- How to verify it after you sign
- Three questions that surface the concurrency behind a quote
- FAQ
Why a chat quote without concurrency isn’t a quote
A voice agent handles one call. A human chat agent handles several conversations at the same time — that’s the entire economic reason chat costs less per contact than a phone call.
But concurrency isn’t a free lunch. It’s the single lever that sets both numbers a buyer cares about, and it moves them in opposite directions:
| Concurrent chats per agent | Cost per chat | Realistic in-conversation wait |
|---|---|---|
| 1 | Highest | Near-instant replies |
| 3 | Roughly one third | Short gaps between replies |
| 5 | Roughly one fifth | Noticeable pauses, especially mid-troubleshooting |
| 7+ | Cheapest on paper | Customers start repeating themselves |
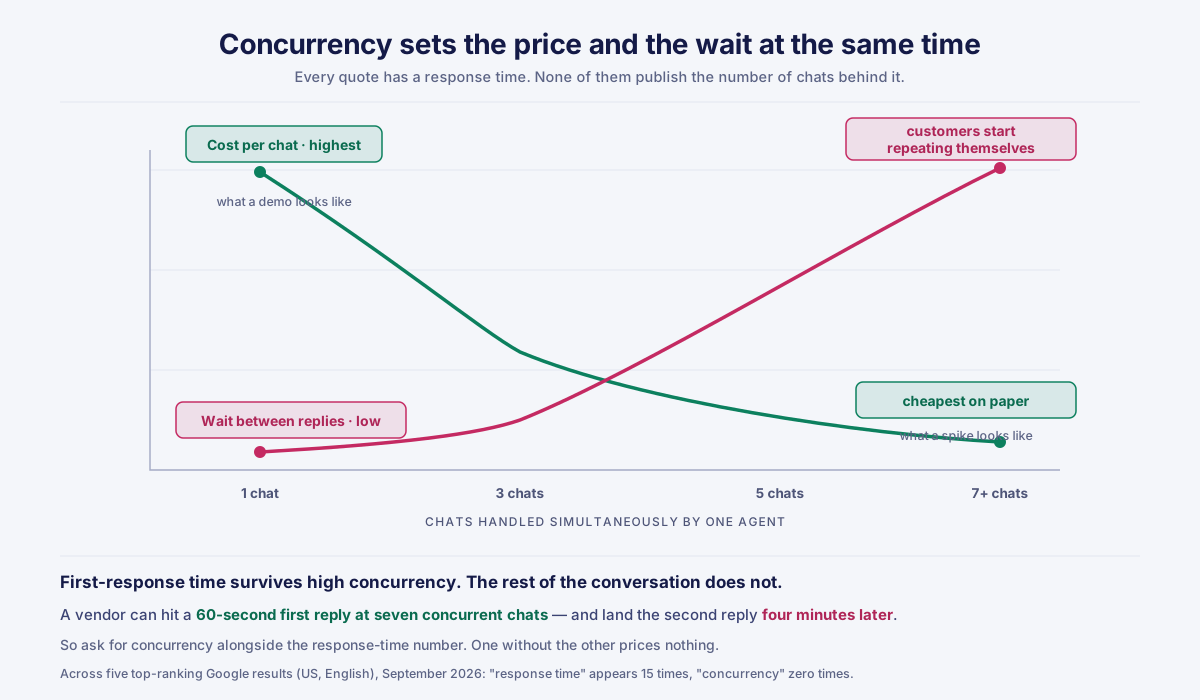
A vendor can quote you an hourly rate and a sixty-second first-response target and be telling the truth about both — while running agents at seven concurrent conversations, where the second reply lands four minutes later. First response is a metric that survives high concurrency. The rest of the conversation isn’t.
This is the same failure pattern as deflection rate: a number that looks like service quality but actually measures something else. If your vendor reports first-response time and nothing else, the report is measuring their routing software, not their staffing.
What to ask instead
Three questions turn an unverifiable quote into a checkable one:
- What is the concurrency cap per human agent, and is it enforced by the platform or by supervisor judgment? A cap that exists only as guidance isn’t a cap during a volume spike.
- What is the P90 in-conversation response time, not the first-response time? The ninetieth percentile of replies inside a conversation is where concurrency shows up.
- What happens to concurrency during a spike? If the answer is “human agents take more chats”, the SLA you signed silently degrades exactly when you need it.
Ask those three and the conversation changes from marketing to operations.
Who takes which chat
The second thing a chat quote rarely spells out is the division of labor: which conversations belong to a machine and which belong to a person.
Route by the cost of getting it wrong, not by channel:
| Chat scenario | Route to | Cost of getting it wrong |
|---|---|---|
| Order status, first ask | AI | Low. The tracking record answers it, and the answer is the same at 3 a.m. |
| Order status, second ask about the same order | Human | High. This is the conversation before a chargeback |
| Return eligibility and label generation | AI | Low. Your policy is a rule, and rules are what automation is for |
| Refund not received, or charged twice | Human | High. Money moving the wrong way is never a routine ticket |
| Pre-sales sizing or compatibility question | AI, escalate on intent | Medium. Speed beats perfection unless the question implies a large order |
| Complaint that names a person or threatens a review | Human | High. Reputation damage isn’t recoverable by replying quickly |
| Anything touching payment data or account access | Human by policy | High. This is a compliance boundary, not a judgment call |
Two things follow from a table like this. First, it’s auditable — you can sample last month’s transcripts and check whether routing actually matched it. Second, it exposes the billing question that vendors rarely raise on their own: when the AI hands a conversation to a person, does anyone charge you for the AI’s failed attempt? That answer varies by platform, and we compared how the major ones handle it in who pays when AI hands off to a human.
What outsourced live chat support services actually cost
Callnovo public pricing, so you can do the arithmetic before anyone calls you.
| Unit | Rate | This is for |
|---|---|---|
| Per interaction — chat, email, social, ticket | US$0.20 | High-volume, low-complexity queues where you already know the mix |
| Dedicated agent | from US$5.80 per hour | A named person on your brand, your KPIs, your training |
| Hire a team | US$5–12 per productive hour | Skill- and language-dependent; engagements run half a seat to 200+, not a five-seat floor |
| Shared team | from US$300/month (500 minutes) or from US$650/month (1,500 minutes) | Steady low volume without a dedicated headcount |
| Pay per resolution — simple | US$0.79–1.49 | FAQ, order status, password resets |
| Pay per resolution — standard | US$1.50–3.49 | Returns, billing, troubleshooting |
| Pay per resolution — complex | US$3.50–6.99 | Technical support, escalations, multi-turn handling |
Volume tiers apply to resolution pricing: standard rates up to 500 per month, 10% off between 500 and 2,000, 20% off above that (Callnovo, 2026).
Notice that these units answer different questions. Per-interaction pricing is honest when your volume is predictable and your conversations are short. Per-resolution pricing moves the risk of a failed conversation onto the provider — an unresolved case costs you nothing, which means the provider’s margin improves only when the automation and the training genuinely work.
Chat support process outsourcing isn’t the same purchase as hiring chat agents. If you buy hours, you own the process design, the routing table, and the concurrency decision. If you buy resolutions, the provider owns them and is paid on the outcome. Both are legitimate; the mistake is buying one and expecting the accountability of the other.
Dedicated live chat outsourcing vs a shared team
The staffing model decides who is on the other end of the chat, and it changes what you can hold the provider to.
| Dedicated | Shared | |
|---|---|---|
| Who answers | Named human agents who work only your queue | A pool of human agents answering for several brands |
| What you control | Interviews, KPIs, training, and the concurrency cap | Hours and scripts inside a fixed package |
| How it’s billed | By the hour, from US$5.80 | By the month, as a package |
| Fits | Queues where a wrong answer is expensive | Steady low volume where speed matters more than depth |
A dedicated arrangement gives you named human agents who learn your catalog. Shared coverage is cheaper and works for queues where product knowledge matters less than speed. Most buyers end up blended: dedicated human agents on the queues where errors are expensive, shared coverage overnight. The trade-offs run deeper than price, and we worked through them in shared vs dedicated customer service agents.
When you outsource live chat operators rather than outcomes, tenure becomes the number to ask about. Callnovo.ai staffs these queues with native speakers across 65+ languages, and average human agent tenure is 4.2 years against an industry average of 1.1 years (Callnovo, 2026). A human agent who has been on your account for three years knows things that can’t be trained in three weeks. On chat there’s no tone of voice to soften a wrong answer, so that difference is visible in the transcript.
24/7 live chat outsourcing: nights and weekends
Out-of-hours coverage is often what sends a brand looking for a chat provider. The in-house team goes home at six, and the chat window stays open. There are three ways to cover those hours, and they aren’t priced or measured the same way.
- Staffed around the clock. Human agents answer at every hour. Callnovo.ai runs this as follow-the-sun coverage, 24/7 (Callnovo, 2026). Ask whether the overnight concurrency cap is the same as the daytime one. A thin night shift is where seven chats per agent quietly becomes normal.
- AI overnight, people in the morning. Automation answers the rows of the routing table marked low-cost, and anything else is queued for a human with the transcript attached. This is the cheapest option, and it only works if the hand-off is logged and somebody owns the morning queue.
- Blended. AI answers first at all hours, and a smaller human team stays on for refunds, complaints, and account access.
Whichever you choose, ask for response times segmented by hour. A monthly average hides the Saturday-night number, and Saturday night is when the gap between the promise and the staffing is widest.
How to compare outsourced live chat providers
Put every chat support outsourcing provider’s answers in the same grid. The left column is what to ask. The right column is what a checkable answer looks like.
| Ask each provider | A checkable answer |
|---|---|
| Concurrency cap per human agent | A number, and whether the platform enforces it |
| Response time inside the conversation | P90, reported by hour |
| Pricing unit | Per hour, per interaction, or per resolution, with the rate for each |
| Minimum commitment | Seats, months, or monthly spend, in writing |
| Languages | Native speakers or translation software, per language |
| Quality review | The share of conversations reviewed, and by whom |
| AI hand-off | Whether a failed AI attempt is billed |
Minimum commitment is the row that removes the most vendors before a call. Some providers publish a one-agent start, and enterprise BPOs usually publish no minimum at all. Callnovo.ai takes engagements as small as half a seat and as large as 200+ seats. We compared providers on that one row in customer service outsourcing companies by minimum commitment.
When we’re not the right fit
- Your chat volume is under a few hundred conversations a month. At that level the coordination overhead of any outsourcing arrangement costs more than it saves — keep it in-house until the queue is predictable.
- Your product needs months of domain knowledge before an agent can answer anything useful. Shared coverage won’t work, and dedicated coverage will be expensive enough that hiring may be the better answer.
- The hourly rate is the only number you’re comparing. We won’t be lowest on it, and on a simple single-language queue where concurrency barely matters, the cheapest desk is usually the right call.
How to verify it after you sign
Everything above is a promise until you can measure it. Three things are checkable from month one:
- Concurrency cap — request the platform setting, not the policy document
- P90 in-conversation response time — segmented by hour, so spikes are visible
- Re-contact rate — the share of customers who come back about the same issue within seven days
That third one is the honest metric. Customer satisfaction surveys are easy to game and easy to under-sample; re-contact rate isn’t. If customers return with the same problem, the conversation didn’t solve it, whatever the survey said.
Quality assurance coverage is worth asking about in the same breath. Industry practice is to review 2–5% of conversations. Callnovo runs automated review across 100% of the conversations handled on our HeroDash platform (Callnovo, 2026) — platform-handled volume, not every interaction in every engagement. That matters more on chat than on voice: at 3% sampling, a new human agent can repeat the same wrong phrasing hundreds of times before anyone notices.
The service commitments behind that are published: first-contact resolution at or above 90%, customer satisfaction at or above 85%, and average resolution under two hours.
Three questions that surface the concurrency behind a quote
- What is your genuine human response time for chats that arrive at 7pm on a Saturday? If you don’t know, or the answer is “Monday”, that’s where the purchase decisions are being lost.
- Does your reporting separate automated replies from human replies? If not, your dashboard is measuring your automation, not your service.
- When chat volume spikes, what decides which conversation a human agent picks up? If the answer is human judgment, some conversations are being missed in a predictable and preventable way.
None of these requirements are difficult to meet. They just have to be built for the queue they’re serving — and the first step is asking for the number that nobody volunteers.
For queues where the conversation turns technical rather than transactional, the buyer and the cost model both change; we covered that split in outsourced IT support services.
References
- Callnovo public pricing — https://callnovo.ai/pricing/
Related reading: Outsourced IT support services: two buyers, one search term · Best platforms for AI-led escalation handling